Direct Answer: When developers, digital artists, and policy researchers search for an uncensored AI image generator, they are typically contrasting cloud-hosted text-to-image APIs—which enforce automated pre-prompt classifiers and post-generation filters that frequently trigger false positives on benign medical, historical, or creative prompts—against local open-weight diffusion models (such as Flux.1, Stable Diffusion XL, and SD 3.5 running in ComfyUI). Understanding how this three-stage safety architecture works helps creators resolve false-positive blocks while adhering strictly to legal, copyright, and ethical boundaries.
1. How Cloud AI Image Generators Enforce Three-Stage Content Moderation
Commercial cloud image platforms (such as OpenAI DALL-E, Midjourney, Adobe Firefly, and Google Imagen) operate as multi-tenant web services subject to enterprise brand-safety standards, payment-processor rules, and statutory compliance. Rather than relying on a single filter, modern cloud text-to-image systems inspect every request across three distinct technical layers:
- Stage 1 — Pre-Inference Prompt Classifier (Text Guardrail): Before the diffusion GPU ever starts denoising latents, your text prompt passes through a regular-expression blocklist and a lightweight LLM moderation classifier. If a word or phrase scores above a risk threshold, the API aborts immediately with a policy warning.
- Stage 2 — Training-Data Curation & Concept Erasure in Model Weights: Before training or via post-training fine-tuning (such as Safe Latent Diffusion or Unlearning / Ablation of specific CLIP/T5 embedding directions), model creators strip or dampen the model’s ability to represent restricted concepts or living artists’ signature styles.
- Stage 3 — Post-Inference Vision Safety Classifier (Pixel Inspection): After the U-Net or Diffusion Transformer (DiT) decodes the latent tensor into RGB pixels through the Variational Autoencoder (VAE), a secondary computer-vision classifier inspects the output image before returning it to the user’s browser.
2. Why Benign Prompts Trigger False Positives in Cloud Pipelines
A major source of frustration for legitimate professionals—including game concept artists, medical illustrators, cybersecurity educators, and historical textbook designers—is the Scunthorpe problem and skin-tone pixel over-blocking in Stage 1 and Stage 3 classifiers:
- Ambiguous Technical and Artistic Terminology: Photography and 3D rendering terms like “shoot a portrait,” “execute a command,” “master/slave cylinder,” “anatomical torso study,” or “Renaissance marble sculpture” frequently trip naive text classifiers.
- Close-Up Portrait Pixel False Positives: Post-inference vision classifiers (such as the legacy CLIP-based
StableDiffusionSafetyCheckerdocumented in Hugging Face Diffusers) evaluate cosine similarity against pre-computed concept embeddings. Close-up lighting on faces, desert sand dunes, or terracotta pottery can occasionally exceed the cosine threshold and return a black frame.
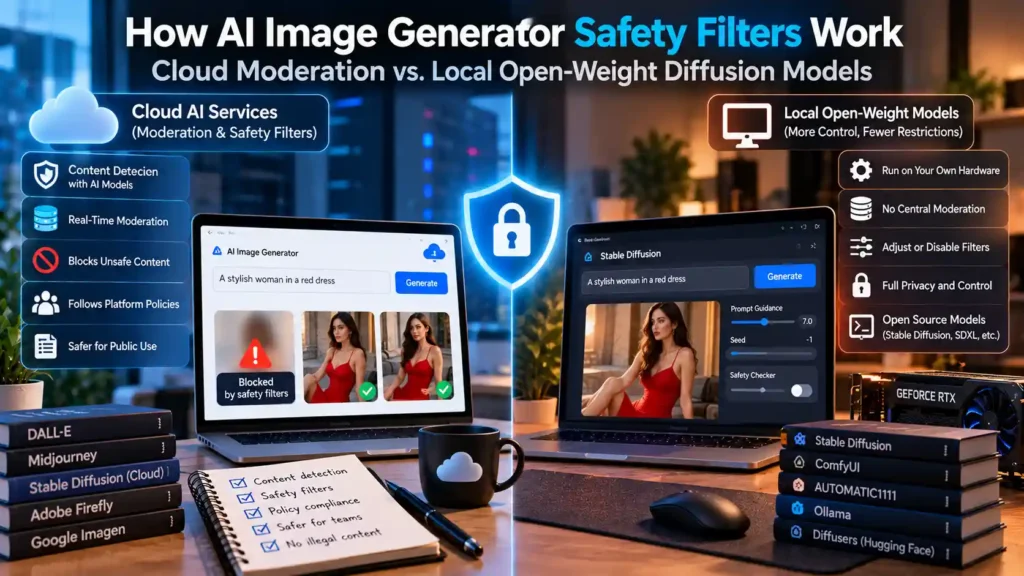
3. Architectural Comparison: Cloud APIs vs. Local Open-Weight Diffusion Models
For studios that require deterministic repeatability, custom ControlNet pose alignment, and freedom from false-positive cloud API lockouts, running open-weight diffusion checkpoints locally on workstation GPUs changes the governance model from external API enforcement to local operator responsibility:
| Architectural Dimension | Cloud Proprietary Generators (Firefly, DALL-E, Midjourney) | Local Open-Weight Models (Flux.1, SDXL, SD 3.5 in ComfyUI) |
|---|---|---|
| Execution Environment | Vendor cloud servers; prompts and outputs are logged for trust & safety review. | 100% local workstation GPU (see our guide on local GPU VRAM sizing for open-weight AI workloads). |
| Moderation Mechanism | Mandatory server-side Stage 1 (Prompt) and Stage 3 (Vision) classifiers. | No external server-side prompt blocker; model capabilities are determined by the base checkpoint weights and license terms. |
| Spatial & Structural Control | Limited to text prompting, basic inpainting, and style references. | Full node-graph control via ComfyUI: ControlNet depth/canny maps, IP-Adapter, Regional Prompting, and custom LoRAs. |
| Provenance & Watermarking | Automatic C2PA Content Credentials and imperceptible watermarks (e.g., SynthID). | Configurable by the developer or publisher; C2PA manifests can be attached via c2patool prior to publication. |
| Commercial Indemnification | Enterprise plans (such as Adobe Firefly) offer IP indemnification for commercial brand assets. | No vendor indemnification; user is solely responsible for license compliance (e.g., Flux.1-dev non-commercial vs. Apache 2.0 Flux.1-schnell). |
4. How Open-Weight Pipelines Operate Locally (ComfyUI & Hugging Face Diffusers)
When you run an open-weight diffusion workflow locally inside ComfyUI or a Python diffusers script, the generation pipeline is decomposed into transparent, inspectable components:
- Text Encoders (
CLIP-L,OpenCLIP-G,T5-XXL): Convert your positive and negative text prompts directly into conditioning tensors on your local GPU without sending text over the internet. - Latent Diffusion / Rectified Flow Transformer (
UNetorMMDiT): Iteratively removes Gaussian noise from a latent tensor guided by your text conditioning and optional ControlNet depth or pose maps. - Variational Autoencoder (
VAE Decode): Translates the denoised latent tensor into a full-resolution PNG or WebP image on your local disk.
Because every node in ComfyUI is local, medical illustrators, game developers creating dark-fantasy combat assets, or cybersecurity teams studying synthetic media detection can iterate without arbitrary account bans—provided their work complies with law and license agreements.
5. Strict Legal, Ethical, and Provenance Boundaries (CSAM, NCII, Copyright & C2PA)
Running open-weight models locally removes automated cloud false positives, but it never removes legal accountability. Every creator, developer, and organization must understand four non-negotiable legal and ethical standards:
- Absolute Prohibition of Exploitative and Non-Consensual Imagery: Generating, possessing, or distributing Child Sexual Abuse Material (CSAM) or non-consensual intimate imagery (NCII / sexual deepfakes of real people) is a severe criminal offense worldwide, regardless of whether an image was produced on a cloud server or a local GPU.
- Right of Publicity and Defamation: Using AI models to fabricate deceptive commercial endorsements or defamatory images of real individuals violates state and federal right-of-publicity and fraud statutes. Read our detailed analysis of right-of-publicity laws and non-consensual synthetic likeness rules for more context.
- Copyright Registration Disclosure: Under current U.S. Copyright Office AI Policy Guidance, purely AI-generated images without meaningful human creative selection, arrangement, or modification cannot be registered for federal copyright protection, and applicants must disclose the inclusion of AI-generated material.
- Transparency and C2PA Provenance: Under frameworks such as the EU AI Act (Article 50), synthetic media published to the public should carry machine-readable provenance metadata. Learn how to verify and attach these signatures in our guide to inspecting cryptographic C2PA Content Credentials and pixel watermarks.
6. Frequently Asked Questions About AI Image Moderation and Open-Weight Models
Why did a cloud AI generator block my completely normal prompt?
Cloud platforms run fast, automated keyword and vision classifiers that frequently misinterpret homonyms (words with multiple meanings), anatomical lighting, or historical/action terminology. Rewording ambiguous terms or switching to a local open-weight workflow in ComfyUI for legitimate creative work resolves false-positive interruptions.
Which open-weight image models allow commercial use?
Always verify the exact license of each checkpoint before commercial use. For example, FLUX.1 [schnell] and Stable Diffusion XL 1.0 permit commercial use under their respective licenses (Apache 2.0 and CreativeML Open RAIL++-M), whereas FLUX.1 [dev] uses a non-commercial license unless you obtain a separate commercial agreement from Black Forest Labs.
Verified Primary Sources & Official Documentation
| Source Name | Source Type | Supported Technical Claim | Verification Status |
|---|---|---|---|
| ComfyUI Official GitHub Repository | Official GitHub Repository | Supports node-based local execution of open-weight diffusion models (SDXL, Flux.1) on consumer GPUs. | Verified Official Repository URL |
| Hugging Face Diffusers Documentation | Official Technical Documentation | Supports how text encoders, latent diffusion schedulers, and optional safety checker pipelines operate. | Verified Official Documentation URL |
| U.S. Copyright Office — Artificial Intelligence Policy Guidance | Government Regulatory Guidance | Supports U.S. copyright registration rules requiring meaningful human authorship for works containing AI-generated material. | Verified Official Government URL |